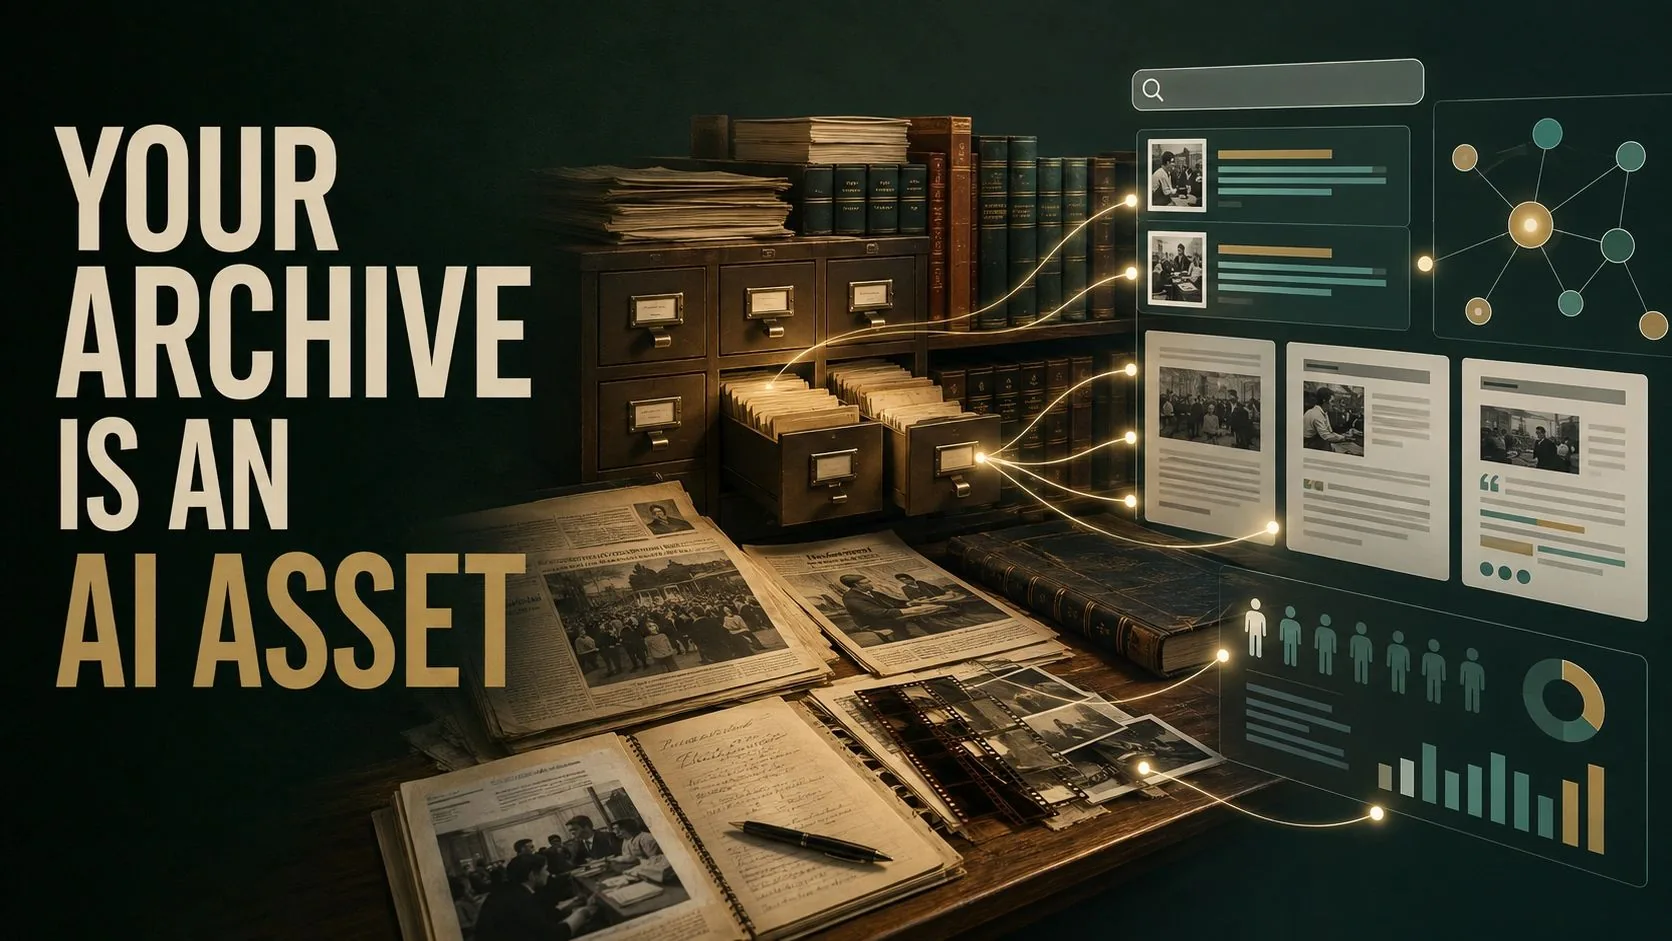
Most media companies describe their archive as a place where old stories live.
That description dramatically understates its value.
An archive is a publisher’s accumulated record of people, places, institutions, events, decisions, investigations, interviews and original observations.
It contains years or decades of reporting that competitors cannot recreate simply by buying another software platform.
That makes the archive more than a storage system.
It is proprietary intellectual property.
It is institutional memory.
And in the era of search and AI discovery, it can become one of a media company’s strongest authority assets.
The opportunity does not come from uploading old files into an AI tool or republishing every article with a new date.
It comes from making the archive accessible, understandable, connected, trustworthy and measurable.
When that work is done well, legacy reporting can continue helping audiences, journalists, search engines and AI systems long after the original publication date.
Why Archives Matter in AI Discovery
Search engines and AI answer systems both need evidence.
They need public pages that provide clear information, identifiable sources and enough context to support an answer.
For publishers, archives often contain exactly that material:
- Firsthand reporting
- Original interviews
- Local and industry expertise
- Named journalists and subject-matter specialists
- Historical context
- Public records and documented events
- Recurring coverage of the same people, companies, communities and topics
- Photographs, graphics, audio and video created by the newsroom
A new article may explain what is happening today.
The archive can explain how the story developed, what happened before, who was involved and why the current moment matters.
That depth helps create a stronger public knowledge footprint.
It also gives a publisher more opportunities to appear for specific questions, long-tail searches and research-driven prompts.
OpenAI states that public websites can appear in ChatGPT search and advises publishers that want their content included in summaries and snippets not to block OAI-SearchBot. Google likewise relies on crawlable pages, internal links, sitemaps and structured information to discover and understand content.
An archive cannot contribute to that discovery if it is effectively invisible.
The Archive Advantage Publishers Already Own
Many media companies are competing for AI visibility by producing more content.
Production matters, but publishers should not overlook the authority they have already earned.
Original reporting
Original journalism is difficult to replicate.
A firsthand interview, local investigation, event recap or historical account may become a source that other sites reference for years.
If the original page remains accessible and clearly attributed, the publisher retains a discoverable connection to that reporting.
Repeated topical coverage
A strong archive often shows that a publication has covered the same community, industry or subject over time.
That repeated coverage can establish depth that a single article cannot.
It helps audiences and machines see that the publisher is not making a one-time claim. It has a body of work.
Entity relationships
Archives naturally document relationships among people, organizations, locations, events and topics.
A local publication may have years of stories about a hospital system, city official, neighborhood, nonprofit, business leader or annual event.
Connecting those stories creates a richer map of the publisher’s expertise.
Historical context
Current information is valuable.
So is accurate historical information.
AI-generated answers frequently need timelines, background, comparisons and explanations. Publishers with trustworthy historical coverage can supply that context—provided the original material is easy to find and interpret.
Brand memory
An archive records what a publication has witnessed and contributed.
It can reinforce the publisher’s identity, editorial mission and community role while distinguishing it from sites that only summarize current information.
Why Valuable Archives Become Invisible
An archive can contain excellent journalism and still perform poorly across search and AI discovery.
The problem is usually not the reporting.
It is the system surrounding the reporting.
Archive pages are blocked or difficult to crawl
Some legacy articles sit behind outdated technology, login walls, robots rules, noindex directives or JavaScript interfaces that do not expose reliable crawlable links.
Other archives are only searchable through an internal search box.
If an article has no crawlable path from the rest of the site, discovery becomes much harder.
Old URLs broke during a redesign or migration
Publishers change domains, content management systems and URL structures.
Without a careful redirect map, high-value articles can become 404 pages or disappear behind new URLs that have lost their prior signals.
Multiple versions compete with one another
Print views, syndicated copies, AMP versions, tag pages, scraped copies and migration duplicates can create several URLs for substantially the same story.
Inconsistent canonical signals make it harder to identify the preferred source.
Metadata is missing or unreliable
Older pages may lack clear titles, summaries, publication dates, modification dates, author pages, image information or Article structured data.
Some migration systems replace the original byline or publication date with the migration date, damaging historical clarity.
The archive has weak internal architecture
Year-and-month folders may preserve chronology without helping users understand topics.
Generic links such as “read more” provide little context. Important stories may sit dozens of clicks from any active page.
PDFs and scanned editions contain inaccessible knowledge
Print archives may live as image-only PDFs, flipbooks or scanned pages without useful HTML summaries or transcripts.
The material exists, but much of its meaning is difficult for search systems, assistive technology and AI tools to process.
The newsroom treats every old page the same
Some legacy articles remain accurate and useful.
Others are outdated, duplicated, thin, legally sensitive or no longer aligned with current editorial standards.
A successful archive strategy requires classification, not blanket preservation or blanket deletion.
What Makes an Archive AI-Ready?
An AI-ready archive is not simply indexed.
It is organized so that people and machines can answer five questions:
- What is this page about?
- Who created it?
- When was it originally published, and was it meaningfully updated?
- How does it relate to other coverage?
- Why should this publication be trusted on the topic?
Building that clarity requires several connected layers.
1. A Complete Archive Inventory
Start by understanding what exists.
Create a URL-level inventory that combines:
- Current URL
- Original URL, when known
- Headline
- Author
- Original publication date
- Last meaningful update date
- Content type
- Topic and location
- Indexability
- Canonical URL
- HTTP status
- Internal links
- External links and citations
- Search impressions, clicks and queries
- Referral or conversion activity
- Known legal, correction or editorial concerns
The goal is not to create a perfect database before acting.
It is to identify patterns, risks and high-value opportunities.
2. A Clear Content Classification System
Every archive page does not deserve the same action.
Use a practical classification model:
Preserve
Keep historically important or accurate original reporting available with its original context.
Prioritize
Identify evergreen articles, exclusive reporting, frequently cited stories and pages tied to commercially or editorially important topics.
Refresh
Update pages when the core subject remains relevant and meaningful new information improves the reader experience.
Consolidate
Combine overlapping pages when several weak or duplicate articles compete for the same intent.
Redirect
Redirect moved or replaced URLs to the closest relevant canonical page when the original no longer needs to remain independently available.
Restrict or remove
Use noindex, access controls or removal when content should not appear publicly because of privacy, legal, safety, licensing or editorial concerns.
This classification should involve editorial, audience, product, legal and technical stakeholders—not SEO alone.
3. Crawlable, Stable Article Pages
High-value archive articles need durable public URLs.
Those URLs should:
- Return the correct HTTP status
- Load the primary article content reliably
- Use crawlable HTML links
- Avoid accidental noindex directives
- Be available to the crawlers the publisher intends to support
- Use a consistent canonical URL
- Appear in an appropriate XML sitemap
- Remain reachable through internal navigation or contextual links
Google recommends that every page a site cares about receive a link from at least one other page on the site. For large or complex publishers, sitemaps can also help search engines discover important URLs more efficiently.
For ChatGPT search visibility, publishers should separately review access for OAI-SearchBot. Training controls and search discovery controls are not the same decision, so crawler policies should reflect the publisher’s actual goals.
4. Accurate Article and Author Signals
Legacy stories should clearly identify the work and the people behind it.
Useful page elements include:
- A descriptive headline
- A concise summary or dek
- The original publication date
- A clearly labeled last-updated date only when a meaningful update occurred
- The journalist’s name
- A link to a persistent author profile
- The publication or publisher identity
- Relevant images with descriptive alt text
- Article, NewsArticle or BlogPosting structured data
- Author and publisher relationships in structured data
Google’s Article guidance specifically supports information such as the headline, images, dates and author identity. Google also recommends consistent visible and structured dates.
Do not change the displayed publication date merely to make an old page appear new.
Historical accuracy is part of the asset.
5. Topic Hubs and Contextual Internal Links
Chronological archives are useful for recordkeeping.
Topic hubs are better for understanding.
A publisher can create authoritative collections around:
- A community or neighborhood
- A company or institution
- A public figure
- An industry
- A recurring event
- A policy issue
- A cultural subject
- A long-running investigation
Each hub should explain the topic, feature the strongest current and historical coverage and link to relevant journalists or contributors.
Articles should also link contextually to earlier reporting where it genuinely helps the reader.
Instead of “read more,” use descriptive anchor text that explains what the linked article contributes.
This builds clearer paths through the archive while showing the relationship between individual stories and the publisher’s broader expertise.
6. Historical Integrity and Transparent Updates
Archive optimization must respect journalism.
There is a difference between improving a page and rewriting the record.
Safe improvements may include:
- Repairing broken formatting or media
- Restoring the original byline and date
- Adding structured data
- Improving accessibility
- Adding descriptive internal links
- Appending a clearly labeled editor’s note
- Linking to a correction, follow-up or current explainer
- Clarifying that information reflects the original publication period
Changes that require stronger editorial review include:
- Altering the article’s factual claims
- Replacing historical language without disclosure
- Removing important context
- Changing quotes
- Updating conclusions as though they were part of the original report
- Using AI to rewrite a journalist’s work at scale
When substantial new reporting exists, a new article may be the better choice. The new page can cite and link to the original.
The archive should preserve truth across time, not create the illusion that every story was written today.
7. Multimedia and Document Accessibility
Media archives often extend beyond HTML articles.
They include:
- Print editions
- Photography
- Audio interviews
- Video
- Podcasts
- Graphics
- Public documents
- Newsletters
For priority assets, add enough surrounding information to make the material understandable:
- A unique landing page
- A descriptive title and summary
- A transcript or accurate text alternative when appropriate
- Creator and contributor information
- Publication and update dates
- Captions and alt text
- Related article links
- Rights and licensing information
This improves accessibility while giving discovery systems more context than a filename or embedded viewer can provide.
8. Measurement That Treats the Archive as a Portfolio
Do not judge archive performance article by article alone.
Measure it as a portfolio of authority.
Useful metrics include:
- Indexed priority URLs
- Search impressions and clicks
- Queries that surface archive pages
- Non-branded discovery
- Referral traffic from ChatGPT and other AI platforms
- External links and citations
- Internal clicks from current stories to archived coverage
- Newsletter sign-ups or subscriptions influenced by archive pages
- Licensing, research or syndication inquiries
- Archive content reused in new reporting
- AI citation share for priority topics
Google Search Console’s Performance report can show queries, pages, clicks, impressions, click-through rate and average position. OpenAI notes that ChatGPT referral links include `utm_source=chatgpt.com`, which gives publishers a direct way to identify that traffic in analytics.
Measurement should answer more than “Did traffic increase?”
It should show whether the archive is becoming easier to discover, more useful to audiences and more connected to business outcomes.
Archive Content With the Highest Activation Potential
Publishers should begin where editorial value and audience demand overlap.
Strong candidates often include:
- Original investigations
- Definitive local histories
- Interviews with notable people
- Profiles of important institutions
- Recurring event coverage
- Evergreen explainers
- Data-driven reporting
- Award-winning journalism
- Frequently linked or cited stories
- Articles already earning impressions but few clicks
- Pages tied to current news cycles
- Reporting that competitors regularly summarize without citing the original source
The best first project is rarely “optimize everything.”
It is a focused collection where the publisher can prove the model.
A 90-Day Archive Activation Roadmap
Days 1–30: Inventory and diagnose
- Export known archive URLs
- Crawl the archive
- Combine technical, editorial and performance data
- Identify broken URLs, duplicates, blocked pages and missing metadata
- Select one priority topic, location or collection
- Establish baseline search, AI referral and citation metrics
Days 31–60: Repair and structure
- Fix priority technical access issues
- Restore original dates and bylines
- Add or repair Article structured data
- Confirm canonical URLs
- Update sitemaps
- Build or improve author profiles
- Create one topic hub
- Add contextual links between current and archival coverage
Days 61–90: Activate and measure
- Publish new reporting that responsibly connects to the archive
- Improve priority multimedia landing pages
- Request recrawling for a limited set of substantially improved URLs
- Track query growth, citations and referral traffic
- Document the editorial and technical workflow
- Decide which collection to activate next
At the end of the pilot, the publisher should have more than a cleaned-up archive.
It should have a repeatable archive operating model.
Common Archive Strategy Mistakes
Mass-deleting old content
Age alone does not make an article useless.
Deletion can remove history, citations, links and authority that cannot be easily recovered.
Republishing old articles as new
Changing a date without meaningful editorial work damages trust and creates confusing signals.
Using AI to rewrite the archive at scale
Automation can assist with inventories, classification, transcripts and metadata suggestions.
It should not silently alter original journalism or remove human editorial accountability.
Creating duplicate “optimized” copies
A second version can compete with the original, split signals and make canonical management harder.
Improve the authoritative page when appropriate or publish a genuinely new story with a clear relationship to the original.
Treating archives as technical projects only
Engineering can repair access.
It cannot decide historical significance, editorial risk or which body of work best represents the publication.
Measuring only sessions
An archive can create value through citations, subscriptions, licensing, research support, journalist efficiency and brand authority—even when a single page is not a high-volume traffic winner.
The Business Value of an Activated Archive
An AI-ready archive supports more than rankings.
It can help a media company:
- Extend the useful life of original reporting
- Strengthen authority around priority topics
- Earn more search and AI citations
- Give journalists faster access to institutional knowledge
- Build richer newsletters and special reports
- Create licensing and research opportunities
- Improve subscription journeys
- Support events, sponsorships and community initiatives
- Differentiate the publication from commodity content
The archive is one of the few assets a publisher already owns that becomes harder for competitors to match over time.
Every year of credible reporting can deepen that advantage.
But only if the work remains accessible and connected.
How to Audit Your Archive as an AI Asset
Begin with five questions:
- Can search and AI crawlers access our priority archive pages?
- Can a reader immediately identify the subject, journalist, publication date and publisher?
- Do our strongest historical stories connect to current coverage and topic hubs?
- Are duplicate URLs, broken migrations or missing canonical signals weakening the original source?
- Can we measure search visibility, AI referrals, citations and business outcomes from the archive?
If the answers are unclear, the archive is not yet functioning as a strategic discovery asset.
That does not mean its value is gone.
It means the value has not been fully activated.
Your Archive Is Already Part of the Future
AI discovery is often discussed as though publishers must build everything from scratch.
They do not.
Media companies already possess years of differentiated reporting, expertise and community knowledge.
The strategic task is to make that work legible again.
Preserve the original record.
Repair the technical foundation.
Clarify authorship and dates.
Connect individual stories into topics and entities.
Measure how the archive contributes to discovery and audience value.
Your next AI visibility advantage may not begin with the next article you publish.
It may already be waiting in the archive.
Sources Used
- OpenAI Publishers and Developers FAQ
- Google Article Structured Data
- Google Publication Date Guidance
- Google Link Best Practices
- Google Sitemap Guidance
- Google Canonicalization Guidance
- Google Noindex Guidance
- Google Search Console Performance Report
Turn Your Archive Into a Discovery Asset
Find out whether your publication’s legacy content is accessible, understandable and positioned to earn visibility across Google, ChatGPT and AI-powered search. Start with The Digital Roots Agency’s AI Visibility Test.
If AI can’t understand you, it can’t recommend you.